The dilemma between data lake or data warehouse tends to appear when the company has already noticed that its data is scattered, reports take too long to come out, and each area works with a different version of the information. At this point, the decision is no longer just technical. It begins to impact cost, governance, analytical speed, and the capacity to scale BI, AI, and automation initiatives safely.
Choosing poorly can mean more rework, fragile pipelines, and an expensive environment that does not keep up with the business. Choosing well creates a foundation to integrate sources, reduce operational bottlenecks, and transform raw data into applied intelligence.
Data lake or data warehouse: the real difference
In practice, the data warehouse was designed for structured analysis, with organized, standardized, and query-ready data. It serves very well scenarios where the business needs reliable indicators, consistent panels, and high predictability in data reading. It is the model that typically sustains management reports, financial monitoring, commercial performance, and critical operational metrics.
The data lake follows different logic. It was created to store large volumes of data in different formats — structured, semi-structured, and unstructured. Logs, files, system events, documents, images, and sensor data can coexist in the same environment. This gives flexibility for more advanced use cases, such as data science, machine learning, massive processing, and not yet fully defined analytical exploration.
The central difference is not only in the type of storage, but in when structure is applied. In the warehouse, modeling and standardization come before consumption. In the lake, data can enter first and be treated as analytical needs evolve.
When the data warehouse makes more sense
If the priority is strong governance, indicator reliability, and analytical consumption by business areas, the data warehouse tends to deliver value faster. It is especially efficient when the company already knows which questions it needs to answer and depends on auditable metrics for decision-making.
Think of operations that require consistency between controlling, sales, supply chain, and customer service. In these contexts, having a lot of data is not enough. It is necessary to guarantee a single definition of revenue, margin, productivity, SLA, and delinquency, for example. The warehouse helps consolidate this reliable information layer.
Another relevant point is user experience. BI, finance, and operations teams typically need to query data quickly, without navigating complex technical structures. A well-modeled warehouse simplifies this access and reduces dependence on the engineering team for recurring analyses.
But there is a trade-off cost. Since the structure needs to be designed more rigorously, bringing in new sources and new use cases can be slower. In companies that change very quickly or work with varied format data, this can limit agility.
When the data lake stands out
The data lake gains strength when the problem is not just consolidating indicators, but expanding the capacity for data capture, storage, and exploration at scale. It is useful for companies with complex environments, high transactional volume, or the need to integrate multiple sources without blocking operations with excessive modeling at the start.
This happens frequently in industry, retail, logistics, telecom, and digital operations with high event generation. In these situations, discarding data because it does not yet have a defined use can be a strategic mistake. The lake preserves this asset and allows the organization to develop new analytical products, predictive models, and automations over time.
It is also a natural path for corporate AI initiatives. Machine learning models depend on variety, history, and granularity. A well-governed data lake creates the foundation for this type of evolution. The critical point lies precisely in the term well-governed. Without catalog, access control, quality standards, and traceability, the lake can become a confusing and unreliable repository.
The most common mistake: treating the choice as a dispute
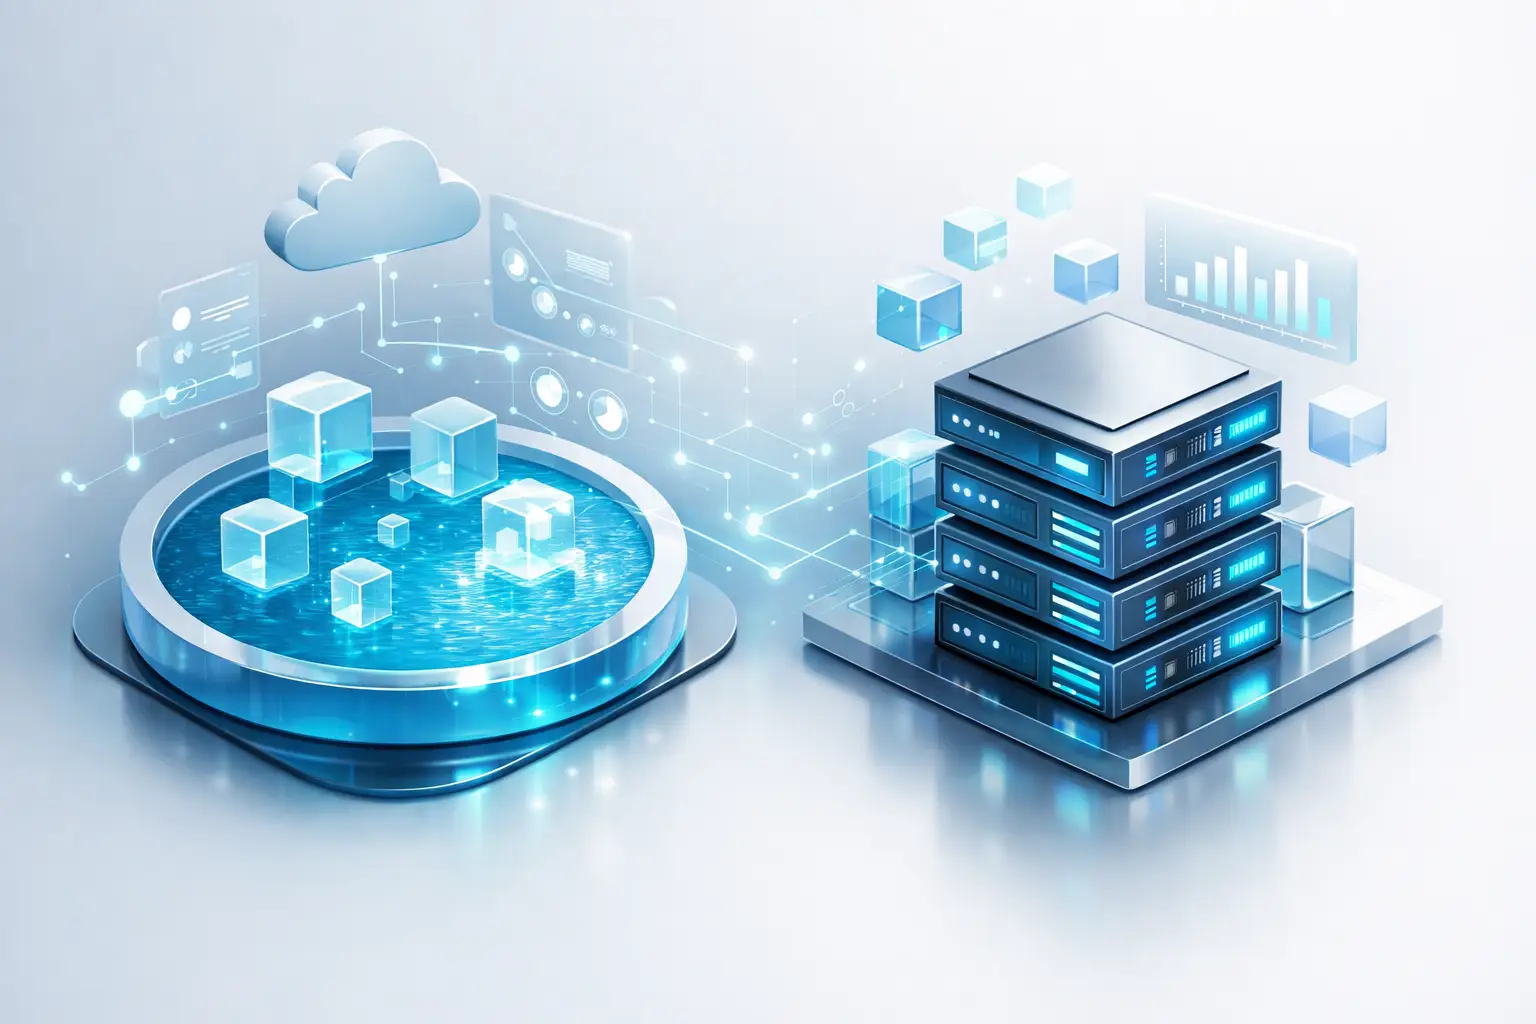
Many companies still discuss data lake or data warehouse as if it were necessary to choose a single winner. In more mature corporate environments, this opposition tends to be limiting. The most efficient scenario, in many cases, combines both models within a modern data architecture.
The lake receives data from multiple sources with scale and flexibility. The warehouse organizes and makes part of that data available for structured analytical consumption, with business semantics and predictable performance. This approach reduces friction between exploration and governance.
Instead of asking which technology is better in the abstract, the right question is different: what type of decision does the business need to make, at what speed, with what level of confidence, and from which data? The answer guides the architecture.
How to decide with business criteria
The decision between data lake or data warehouse needs to start from three dimensions: objective, maturity, and operations. If the main objective is to consolidate indicators and standardize reports, the warehouse tends to be the most rational starting point. If the goal is to integrate large volumes of heterogeneous data and prepare ground for advanced analytics, the lake tends to be more adherent.
Maturity also weighs. Organizations with low data governance and poorly defined processes may become frustrated adopting a lake without operational discipline. Companies with more structured data engineering can extract more value from this model. The same applies to the warehouse: without alignment of business rules between areas, the consistency promise does not hold.
Finally, there is the operational dimension. Can your team sustain pipelines, monitoring, catalog, security, and continuous evolution? Data architecture is not a one-time project. It is a permanent capability. When this vision is lacking, the environment ages quickly and becomes a bottleneck instead of an accelerator.
Costs, performance, and scalability
Cost is another factor frequently poorly assessed. There is a perception that the data lake is always cheaper, because it stores raw data with greater flexibility. In storage terms, this may be true. But total cost is not just in storage. It includes processing, organization, governance, observability, and technical effort to make data usable.
Similarly, the data warehouse may seem more expensive at the start, but generate quick return when it reduces inconsistency, accelerates reports, and improves decision-making in critical areas. What weighs on the budget is not just the technology chosen, but the architecture design, consumption pattern, and level of operational waste.
In cloud environments, this calculation becomes even more strategic. Managed services allow scaling on demand, but require careful design to avoid unnecessary processing, data duplication, and low query efficiency. Performance without governance tends to become a high bill.
Governance is not a technical detail
If there is one topic that separates successful initiatives from environments that lose value over time, that topic is governance. It does not matter whether the company chose data lake, data warehouse, or a hybrid model. Without a clear policy of access, quality, classification, and lineage, confidence in data deteriorates.
For the business decision-maker, this appears simply: divergent numbers, delay in delivering analyses, audit difficulty, and low adoption by user areas. For the technical team, it appears as rework, constant corrections, and excessive dependence on specialists who know the environment informally.
Efficient governance does not mean bureaucracy. It means creating criteria so that scale does not compromise security, compliance, and usability. This is what allows transforming a data initiative into a genuine corporate asset.
The ideal architecture depends on the company's stage
Companies at an early stage of analytical maturity may obtain more results starting with a reliable analytical layer, focused on priority indicators and integration of main sources. Organizations dealing with multiple systems, IoT, near-real-time data, and AI initiatives may need a more flexible foundation from the start.
In many projects, the best answer is not to replace everything, but to modernize in stages. Create a scalable foundation, organize the most critical data domains, and evolve architecture according to value generated. This path reduces risk, preserves investments, and avoids decisions driven by trend rather than real need.
It is precisely in this type of context that specialized consulting makes a difference. More than implementing technology, the role is to align architecture, operations, and business strategy so that data stops being a dispersed liability and begins sustaining efficiency, automation, and growth. For ST IT Cloud, this alignment is what transforms data modernization into measurable results.
The best choice between data lake or data warehouse rarely comes from a generic market definition. It comes when the company understands what it needs to solve now, what it wants to scale in the next few years, and what level of discipline it is willing to sustain. When this reading is done well, architecture stops being a technical bet and becomes a competitive advantage.