A pump that stops without warning can interrupt an entire line, compromise delivery deadlines, and increase emergency maintenance costs. This is the point where a predictive maintenance use case ceases to be just an Artificial Intelligence initiative and becomes an operational decision with direct impact on availability, margin, and risk.
The proposition is simple in theory: use equipment data to identify degradation signals before a failure occurs. In practice, the result depends on an architecture capable of collecting reliable signals, contextualizing them with operations, and transforming predictions into work orders that make sense to the maintenance team.
What characterizes a predictive maintenance use case
Corrective maintenance happens after the failure. Preventive maintenance follows a calendar or a fixed usage metric, such as operating hours or cycles. Predictive maintenance estimates the actual condition of the asset based on historical data and signals observed in near real time.
This does not mean all machines need new sensors or complex models. A well-structured project starts with asset criticality and the cost of its downtime. In many industrial environments, data already existing in SCADA systems, PLCs, historians, ERPs, and maintenance management platforms contain sufficient signals to start the analysis.
The focus is not on predicting any anomaly. It is on answering questions that support concrete decisions: which equipment has the highest probability of failure in the coming days? Which variable is deviating from expected behavior? Which intervention should be prioritized in the next maintenance window? What is the impact of postponing that action?
Practical example: monitoring critical pumps
Consider an industrial operation with centrifugal pumps responsible for feeding a continuous production stage. A failure in one unit can reduce capacity, affect product quality, or require an unplanned shutdown. Although the plant has periodic inspections, there are cases where wear progresses between one round and the next.
In this scenario, the company can integrate vibration data, bearing temperature, suction and discharge pressure, flow rate, power consumption, rotation speed, and accumulated operating hours. These signals gain more value when crossed with contextual information, such as fluid type, load regime, intervention history, replaced parts, and previous occurrences.
An isolated temperature rise, for example, does not confirm a failure. It may result from a temporary load change or environmental conditions. But a gradual increase in temperature associated with vibration changes and higher energy consumption may indicate misalignment, cavitation, bearing wear, or loss of hydraulic efficiency.
The analytical model does not replace the technician's evaluation. It prioritizes human attention by pointing out equipment with out-of-pattern behavior and by presenting the variables that explain the alert. This way, the team stops inspecting all assets with the same intensity and starts concentrating resources where the operational risk is higher.
From telemetry to maintenance decision
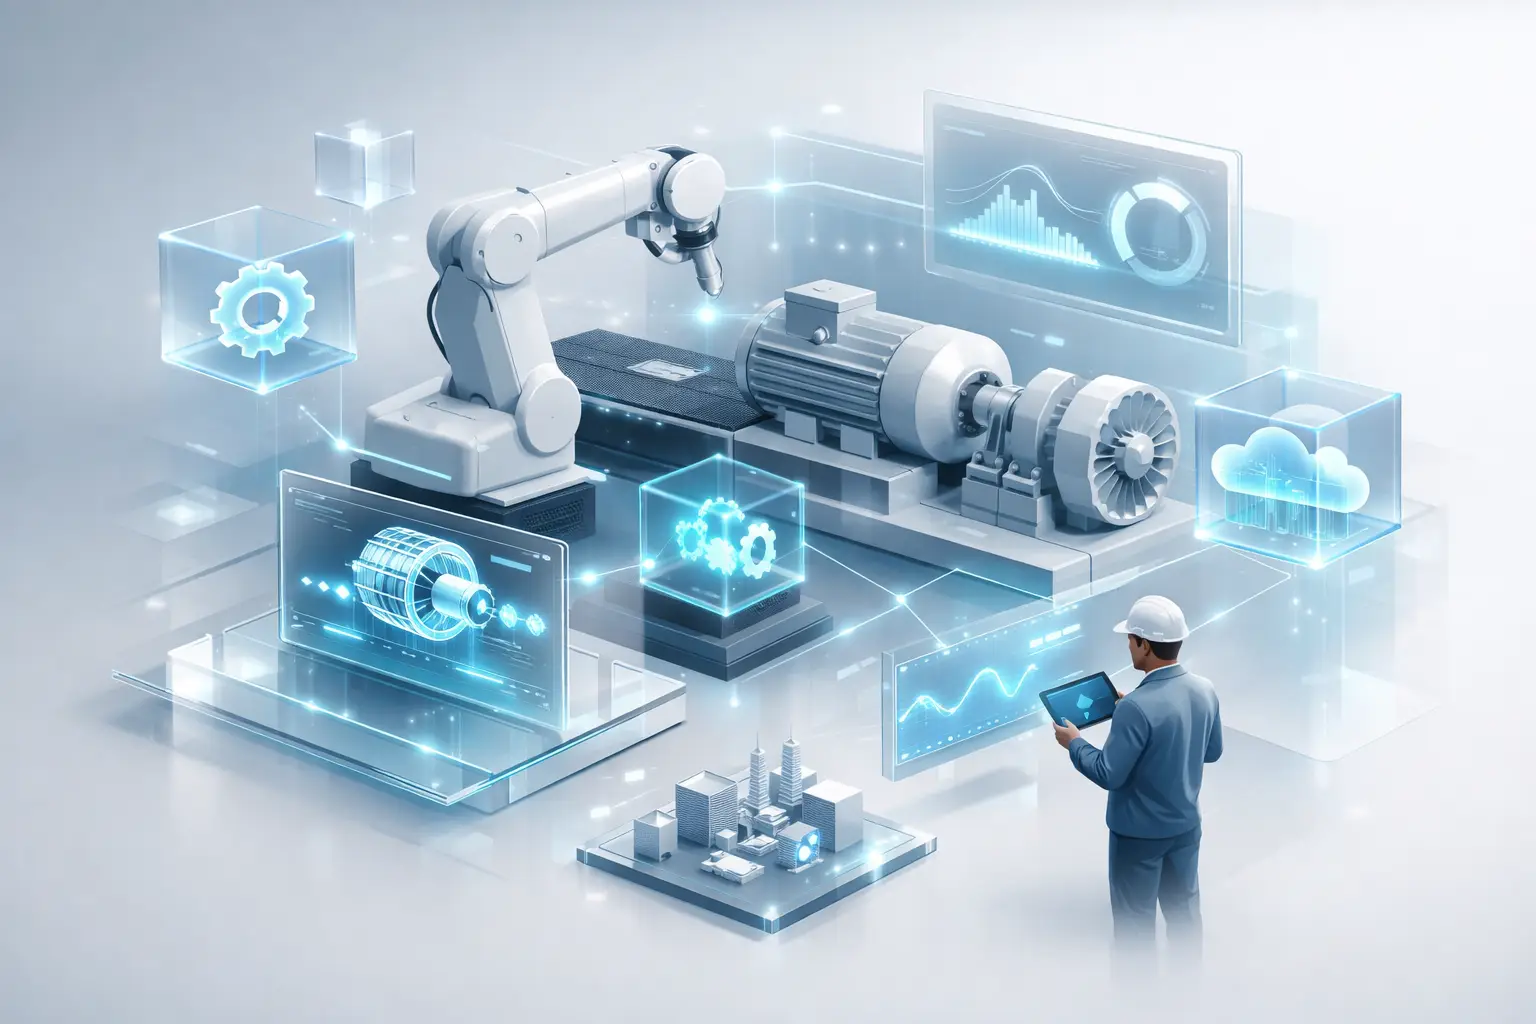
The flow starts at the edge, with data capture by sensors, industrial gateways, or integrations with existing systems. The transmission must consider connectivity, security, and operational continuity requirements. In plants with limited connectivity, part of the processing can occur locally, with subsequent sending of consolidated data to the cloud.
In the data layer, readings need to be standardized, validated, and linked to the correct record of each asset. This point seems operational, but it usually determines the success of the initiative. Inconsistent tags, sensors without calibration, history gaps, and poorly detailed maintenance records reduce the reliability of any model.
In a modern AWS architecture, services such as AWS Glue and Amazon EMR can support the preparation and processing of large volumes of historical data. Functions with AWS Lambda can automate treatments and alerts, while dashboards in Amazon QuickSight provide visibility into equipment health indicators, anomalies, and performance of executed actions.
After preparation, analytical techniques come into play. For assets with a reliable failure history, supervised models can estimate failure probability or remaining useful life. When failure events are rare — which is common in well-maintained equipment — anomaly detection models tend to be more suitable. They learn the normal operating pattern and flag relevant deviations.
The output must reach the maintenance process with objective criteria. Instead of a generic alert, the team needs to receive something like: “pump B-14 with elevated risk index, progressive vibration increase on the X-axis, estimated availability impact, and recommendation for inspection at the next scheduled shutdown.”
Where the financial return lies
The gain does not simply come from deploying sensors or a Machine Learning model. It appears when the company reduces unplanned downtime, prevents secondary damage, improves parts planning, and increases mean time between failures.
In an operation with critical equipment, a planned intervention tends to require fewer resources than emergency maintenance. The team can schedule labor, make the right part available, choose a window with less production impact, and prevent an initial failure from causing damage to other components.
There is also a gain in inventory management. When maintenance can anticipate risks with a reasonable level of confidence, the company reduces both the urgency of purchases and the need to maintain excess high-cost parts. The balance depends on replenishment time, item criticality, and the cost of downtime.
To measure results, it is recommended to monitor indicators such as reduction of unplanned downtime, cost per work order, mean time to repair, mean time between failures, asset availability, and alert accuracy. The most relevant indicator varies according to the business objective. In a continuous process plant, availability may be the key metric. In a fleet, the focus may be on maintenance cost per kilometer and route compliance.
The limits that must be considered
Predictive maintenance is not a solution indicated for all assets. Low-cost, easily replaceable equipment with little influence on production may be better served by preventive or planned corrective strategies. Applying sensors and advanced models in these cases can cost more than the expected benefit.
Another limit is data quality. If the failure history does not identify the cause, affected component, date, and operating condition, the model will have difficulty generating reliable recommendations. Before expanding the initiative, many organizations need to evolve basic processes of record-keeping, asset taxonomy, and data governance.
There is also the risk of alert overload. A system that flags deviations with no operational relevance quickly loses credibility. That is why risk thresholds, escalation rules, and the interface with technicians must be continuously calibrated. Field team experience is an essential part of that adjustment.
How to structure implementation with lower risk
The most consistent path is to start with a controlled scope: a group of critical assets, a relevant failure, and a measurable value hypothesis. Instead of trying to monitor the entire plant, the company can select equipment with a history of downtime, high repair cost, or direct production impact.
The next step is to assess data availability, quality, and frequency. Then it is necessary to build the operational baseline, understand how the equipment behaves under normal conditions, and define what will be considered a useful alert. Only then should the model be integrated into maintenance flows and management dashboards.
ST IT Cloud supports this type of journey by connecting data architecture, IoT, Cloud, and Artificial Intelligence to clear operational objectives. The priority is not just generating predictions, but creating a secure, scalable, and governed foundation so the maintenance team can make decisions with confidence.
The best first step is to choose a failure that is costly today, gather available data, and calculate the value of preventing it. When prediction begins to guide a planned action on the factory floor, technology stops being a promise and starts protecting the operation.