When operations start suffering from delayed reports, inter-area rework, and difficult-to-maintain pipelines, the comparison between ETL and ELT stops being an isolated technical discussion and becomes an architecture decision with direct effect on cost, scale, and speed of business response. For companies modernizing their data environment, choosing between these approaches changes how information circulates, how governance is applied, and how analytical intelligence gains traction.
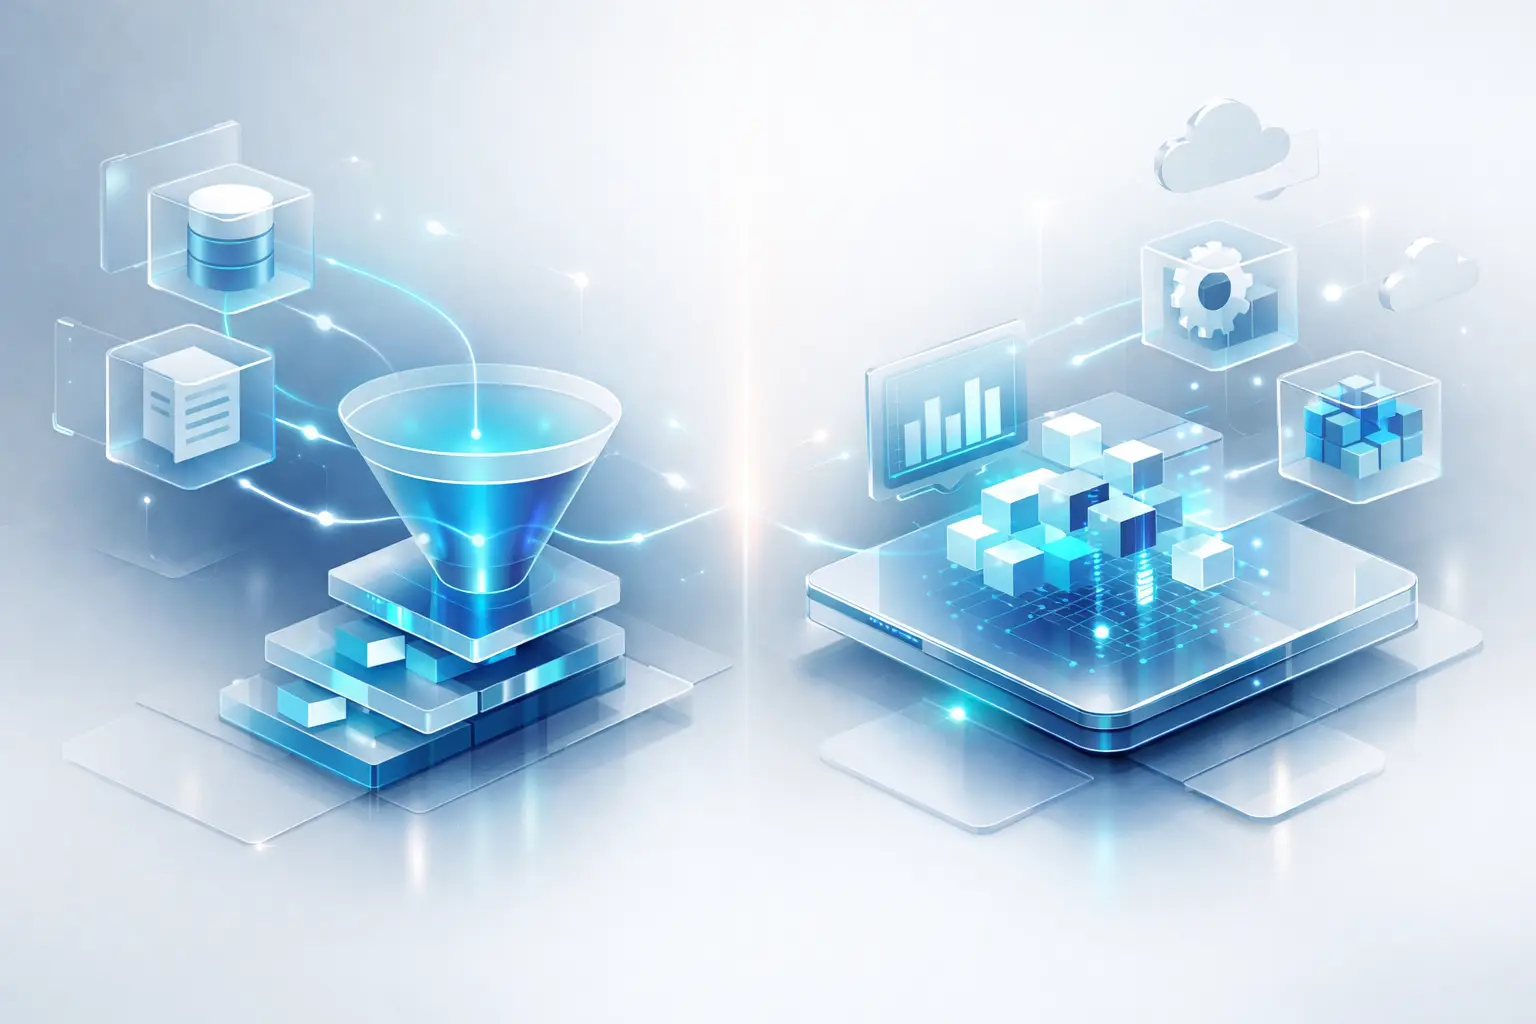
The central difference seems simple. In ETL, data is extracted from sources, transformed first, and only then loaded into the destination. In ELT, data is extracted, loaded first into an analytical repository, and transformed later, already within the destination platform. In practice, however, this choice involves computational capacity, cloud architecture, data volume, regulatory requirements, and operational maturity.
Comparative between ETL and ELT: what really changes
ETL was for many years the standard in corporate environments. It makes sense in contexts where the company needs to strongly control quality and standardization before any data enters a data warehouse. This logic was born in an era of more rigid infrastructure, more expensive analytical databases, and less computational elasticity.
ELT grew alongside cloud platforms and modern data architectures. With more processing capacity at the destination, it became viable to load large volumes quickly and transform later, according to analytical, operational, or regulatory needs. This accelerates data availability and broadens flexibility for different uses.
The most relevant change is not just in the order of steps. It is in where computational effort happens, how teams consume data, and how quickly the company can adapt its analytical model to new demands. In a scenario of digital expansion, system merging, omni-channel, or AI application, this difference weighs considerably.
When ETL makes more sense
ETL remains a solid choice in many corporate contexts. Companies with highly defined business rules, strong entry validation needs, and environments where only already-treated data can proceed to consumption find value in this approach. In regulated sectors, for example, pre-processing and sanitizing information before loading can reduce inconsistency and improper exposure risks.
Another important point is predictability. Since transformation occurs first, data tends to arrive more organized at the final destination. This facilitates consumption by traditional reports, stable panels, and less dynamic analytical structures. For operations that prioritize consistency and control above agility, ETL still delivers well.
The trade-off appears in scalability and speed of change. The more sources, rules, and integrations enter the scene, the more complex and costly the pipeline can become to maintain. Changing transformations in an extensive ETL flow often requires rework, processing windows, and greater engineering effort.
Where ELT gains competitive advantage
ELT tends to be more adherent to modern data strategies, especially in cloud environments. By loading raw data first, the company preserves granularity and history, opening space for multiple subsequent uses. The same piece of data can feed BI, data science, audit, predictive models, and automations without depending on a single initial model.
This approach also favors speed. Instead of waiting for all transformation to happen before loading, data arrives faster in the analytical environment. This is valuable for organizations that need to reduce latency between information generation and decision-making. In commercial, industrial, financial, or logistics operations, this time makes a concrete difference.
Furthermore, ELT combines well with scalable cloud services, where processing and storage can grow according to demand. This reduces typical legacy environment bottlenecks and allows adjusting architecture to the business pace, not the opposite.
But ELT is not automatically better. If governance is weak, loading everything without criteria can create a confusing environment, raise processing costs, and increase misuse risk. ELT without architectural discipline turns into data accumulation, not applied intelligence.
Cost, performance, and maintenance
In a comparison between ETL and ELT, a common mistake is evaluating only licensing or tools. The real cost lies in the sum of infrastructure, maintenance effort, processing time, rework, and operational impact.
In ETL, a relevant part of cost can concentrate in the transformation layer, which must support validations, enrichments, and complex rules before loading. Depending on the technology used, this can mean heavier intermediate environments and greater dependence on batch processes.
In ELT, cost shifts to the destination environment, which needs capacity to process transformations internally with efficiency. In well-designed cloud platforms, this tends to work better because the model is more elastic. Even so, without query optimization, partitioning, orchestration, and usage governance, the bill can grow quickly.
In maintenance, ELT tends to offer more agility for analytical evolutions. Since raw data is already available, creating new transformations or testing new views is simpler. In ETL, structural changes can be slower because they affect the flow before loading.
Governance and security are not details
The discussion between ETL and ELT cannot be separated from governance. It is not enough to move data quickly if the company does not know who accesses it, what was transformed, which rules are in force, and how to ensure traceability.
In ETL, governance tends to rely on the idea that only validated data enters the analytical environment. This creates a strong control layer at entry. In ELT, governance needs to be designed more broadly, with data zones, profile-based access control, cataloging, transformation versioning, and audit trails.
For companies in regulated sectors or with high data sensitivity, this is decisive. The right model is not the most modern in theory, but the one that sustains compliance, security, and scalability without halting operations. This is why data architecture should not be treated as a tool choice, but as a business decision with a technical foundation.
ETL or ELT for BI, analytics, and AI
If the company seeks only to feed predictable operational reports, ETL may continue serving very well. If the objective is to expand analytical capacity, integrate multiple sources, work with semi-structured data, and accelerate AI initiatives, ELT generally offers more elasticity.
This happens because advanced analytics projects change frequently. New questions arise, new sources come in, new attributes begin to matter. In an environment highly dependent on prior transformation, each change can cost too much time. In ELT, the raw material is more accessible for later exploration.
Still, there are quite effective hybrid scenarios. Part of the data can follow an ETL pipeline due to regulatory requirement or operational criticality, while another part enters ELT logic for analytical exploration, machine learning, and controlled experimentation. In many mature companies, the answer is not to choose one side and abandon the other, but to coherently combine approaches.
How to decide without creating technical debt
The correct question is not just which approach is better. It is better for which context, with which goals, and under which constraints. If the organization deals with low analytical maturity, fragmented environments, and manual processes, migrating to ELT without a governance model may trade one problem for another. Similarly, insisting on traditional ETL in a fast-growing operation can limit innovation and generate unnecessary bottlenecks.
A consistent decision tends to consider five factors: data volume and variety, latency need, governance requirements, infrastructure elasticity, and analytical consumption profile. It also matters to observe the internal team's capacity to sustain the chosen architecture over time.
This is where specialized consulting adds real value. More than implementing pipelines, the role is to align architecture, security, performance, and business objective. In projects conducted with this vision, such as those ST IT Cloud structures in modern data environments on AWS, the ETL vs ELT discussion stops being theoretical and begins answering a more strategic question: how to transform data into operational efficiency and competitive advantage.
In the end, the best choice is the one that reduces friction between data and decision. If the architecture favors scale, control, and speed in the right measure, it stops being just technology and begins functioning as a concrete foundation for sustainable growth.